Master Data Management (MDM)
MATCH_AND_LINK mode and to use the MDM UI for link management. An MDM module explicitly configured with MDM Mode set to MATCH_ONLY starts and runs without an MDM license. The MATCH_ONLY value must be a literal mdm.mode setting; a placeholder expression such as #{env['MDM_MODE']} is not resolved before the license check runs, so it will not be recognized as MATCH_ONLY and the module will be refused.
Healthcare organizations often depend on multiple systems to deliver care, manage operations, process claims, and exchange information — and each of those systems may maintain its own version of the same patient, practitioner, organization, or other critical entity. As data is consolidated from EHRs, laboratories, pharmacies, claims platforms, registries, and other sources, those separate records often arrive with different identifiers, inconsistent demographics, and incomplete context. Smile CDR's Master Data Management (MDM) restores the single view: it determines which records describe the same real-world person or entity and unifies them, combining a configurable matching engine, automated record linking and merging, and data steward tooling for the cases that need human judgement.
Smile CDR supports a family of MDM strategies for managing this duplication: duplicates can be merged away as data is ingested, records can be linked through a shared enterprise identifier assigned by an external system, or the MDM module can maintain links between source records and a consolidated representation of the real-life entity known as the Golden Record. In the Golden Record approach, the Golden Record id plays the role of a unique identifier for that resource across all of the different source systems. The next section provides guidance on selecting the strategy that best fits your environment.
MDM works for most HAPI FHIR resource types and processes each resource type independently. The following documentation will often use Patient to illustrate MDM use cases since it is the most common resource type MDM is applied to.
Selecting a deduplication strategy
Selecting the right deduplication strategy for your business context involves careful evaluation of data fidelity and performance trade-offs.
In some contexts, it is vital to retain the content of incoming resources exactly as they were received from the original data sources. This may be due to stringent audit requirements, or a need to differentiate data by source during subsequent operations. For instance, there may be one class of user who is only authorized to query or update resources associated with a single source system, while another class of user needs a consolidated view of all information about a patient, regardless of source system. In other contexts, it may be desirable to modify or even discard some incoming data in the name of providing a simpler model to subsequent processing.
Another important consideration is whether the data includes an enterprise identifier (EID). An enterprise identifier is an identifier from a well-known namespace whose values have a 1-to-1 relationship with the real-world entities being described: each entity has exactly one EID value, and all resources that carry the same EID value describe the same entity. An EID may be assigned by the source system, or it may be injected by an upstream entity resolution service — a system that determines when two records refer to the same real-world entity and assigns them a shared identifier. The most common entity resolution service in healthcare is the Enterprise Master Patient Index (EMPI), which resolves patient records. Strategies that link records by EID depend on the EID being reliably present on resources of the types being deduplicated.
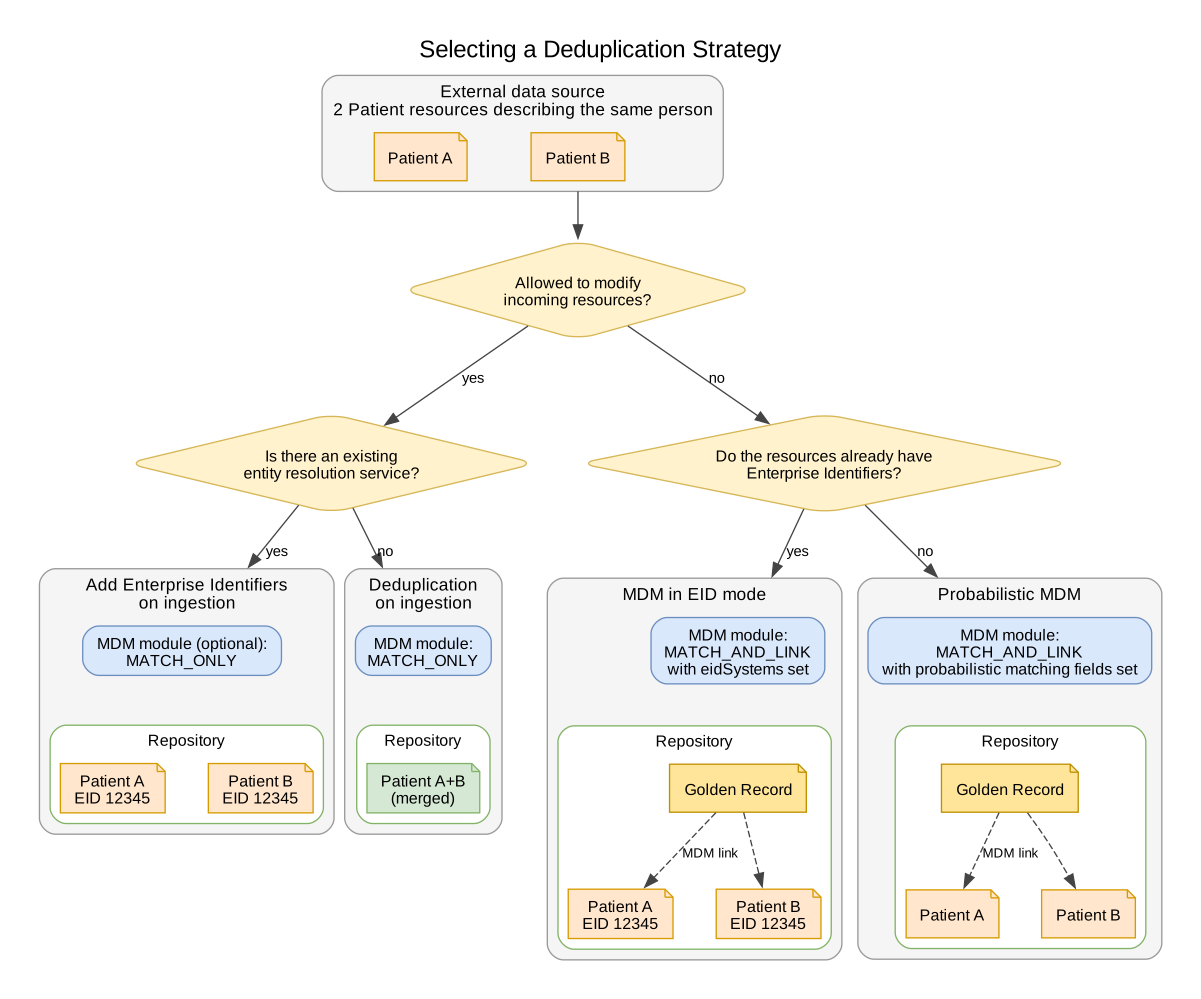
The diagram traces a concrete example: two Patient resources describing the same person arrive from the external data source. How many Patient resources the repository ends up holding depends on the strategy. With Add Enterprise Identifiers on ingestion, both resources are stored and both carry the same EID, so the repository holds 2 Patient resources; no Golden Resources or MDM links are created, and queries collate the records by EID. With Deduplication on ingestion, the incoming duplicate is merged into the existing resource (or dropped) before it is stored, so the repository holds 1 Patient resource. With the two Golden Record strategies — MDM in EID mode and Probabilistic MDM — both source resources are stored unmodified and the MDM module creates a third resource, the Golden Record, linked to each source record, so the repository holds 3 Patient resources.
Add Enterprise Identifiers on ingestion
This strategy requires an external entity resolution service that assigns the enterprise identifier. It is best used when such a service already exists in the deployment environment.
If the incoming resource already contains an EID value, no extra work is necessary - the resource can be persisted as-is. However, some resources may arrive from external systems missing the EID. In such cases, the resource can be intercepted before it is written to the repository and passed to the entity resolution service, which assigns an EID (and perhaps modifies the resource in other ways, such as updating demographic fields). The modified resource is then stored.
Once the EID is in place, the strategy can be run in two ways, differing in how the linked records are retrieved:
- With an MDM module in
MATCH_ONLYmode. DefineeidSystemsin the MDM rules and enable MDM search expansion. Searches using the:mdmparameter modifier, the$everythingoperation with_mdm=true, and Group bulk export then expand automatically to all records sharing the EID. See EID-based MDM expansion in MATCH_ONLY mode. - Without an MDM module. Callers search for the EID using the
identifiersearch parameter (or a chained parameter such aspatient.identifier) and collate the returned resources themselves. See Manual EID queries.
In both cases, no Golden Resources or MDM links are created; the repository holds only the source resources.
Benefits:
- Allows a mature and well-tested entity resolution service to be retained.
- When run without an MDM module, does not require an MDM license.
Drawbacks:
- When run without an MDM module, callers must know the EID, consistently use it in queries, and collate the duplicate resources after retrieval.
- Data ingestion may become unreliable if the external system is unavailable.
Performance considerations
- There may be a slight performance cost associated with insert and update operations, depending on the characteristics of the external entity resolution service.
- When run with an MDM module in
MATCH_ONLYmode, expansion searches for matching EID values at query time; no background MDM processing or message broker infrastructure is required. - When run without an MDM module, there are no server-side implications for queries. However, the search results bundle may be larger than other methods, and require more caller-side processing.
For more details, see Integrating an External Entity Resolution Service.
Deduplication on ingestion
This strategy ensures that no duplicate resources exist in the repository. When an incoming bundle arrives, MDM matching rules compare each resource to existing resources in the repository. When a match is found, the matching resources can either be merged using survivorship rules, or the resource in the bundle can be dropped. Any internal references in the bundle are then updated to point to the resource in the repository.
Benefits:
- Only one resource exists in the repository for each real-world entity. No golden resources will be created. This minimizes the storage footprint of the repository.
- Query results are unambiguous, and all data from all sources is already consolidated.
Drawbacks:
- Requires the repository to be free of duplicates at the start. If the repository already contains data, it must be manually inspected for duplicates and those duplicates must be merged (see Working with Duplicates) before the strategy can be activated.
- Only supports data ingestion via bundles, not individual resources.
- This strategy does not support the
POSSIBLE_MATCHoutcome, since there is no opportunity for a data steward to resolve borderline cases. - It is not possible after the fact to determine what data originated in which source system.
Performance considerations
- One-time processing during ingestion to resolve duplicates. Cost may vary depending on the size and complexity of the bundle, but this step can be turned into an asynchronous background process using Camel.
- Queries are fast, since duplicate data has already been resolved.
For more details, see Deduplication on Ingestion.
MDM in EID mode
This strategy is applicable when every resource of the types being managed by MDM is guaranteed to contain an Enterprise Identifier. This identifier can be a reliable centrally-assigned identifier, such as a jurisdictional provider registry number, or it can be assigned by an upstream entity resolution service in the ingestion pipeline. EID mode establishes linkages efficiently, using the EID value of the incoming record to identify matches with a single search.
Benefits:
- Incoming resources are not modified.
- Matching is quick and unambiguous.
Drawbacks:
- The strategy assumes that the EID will be present on every resource of the MDM-managed types. If it is ever missing, potential matches will be missed. (Note that EID mode can be combined with probabilistic matching to provide fast matches when the EID is present while still finding high quality matches when it is missing.)
- The creation of golden records increases the amount of storage space required.
Performance considerations
- Single-query matching on ingestion minimizes the cost of establishing links.
- MDM link resolution at query-time can be slightly slower than plain queries, but returns more comprehensive data.
For more details, see Golden Record MDM and MDM Enterprise Identifiers.
Probabilistic MDM
This strategy can be applied to any resources without restriction. A user-defined set of matching rules will be applied to incoming resources to establish matches and potential matches to existing golden resources. Potential matches can be confirmed or refuted after review by a data steward.
Benefits:
- Incoming resources are not modified.
- Maximum flexibility and configurability.
- No preconditions on characteristics of the data or on the state of the repository.
Drawbacks:
- Configuration by a system administrator is required. It will not give good results in the default state.
- The creation of golden records increases the amount of storage space required.
Performance considerations
- Matching rules can take some time to evaluate. This is done in a background process, but there will generally be some latency before the results of the linkage are available for query.
- Latency will be longer in cases where a data steward must review a potential match.
- MDM link resolution at query-time can be slightly slower than plain queries, but returns more comprehensive data.
For more details, see Golden Record MDM and MDM Rules.
Cleaning up existing duplicates
The four strategies above manage duplication as data is ingested. Duplicates that already exist in the repository — for example, data accidentally loaded twice, or a backlog of duplicates that must be resolved before activating deduplication on ingestion — are repaired with the repository-level merge operations:
$merge— a backport of the FHIR R5 Patient/$merge specification to FHIR R4.$hapi.fhir.merge— extends merge functionality to all FHIR resource types that have anidentifierelement.$hapi.fhir.replace-references— updates all references from one resource to another without merging the resources.$hapi.fhir.undo-mergeand$hapi.fhir.undo-replace-references— undo the effects of a previous merge or reference replacement.$sdh.mdm-deduplicate- uses existing mdm rules to find exact matches and merge them
These operations are documented in Working with Duplicates. They operate directly on source resources; the $mdm-merge-golden-resources operation, in contrast, merges two Golden Resources maintained by the MDM module.
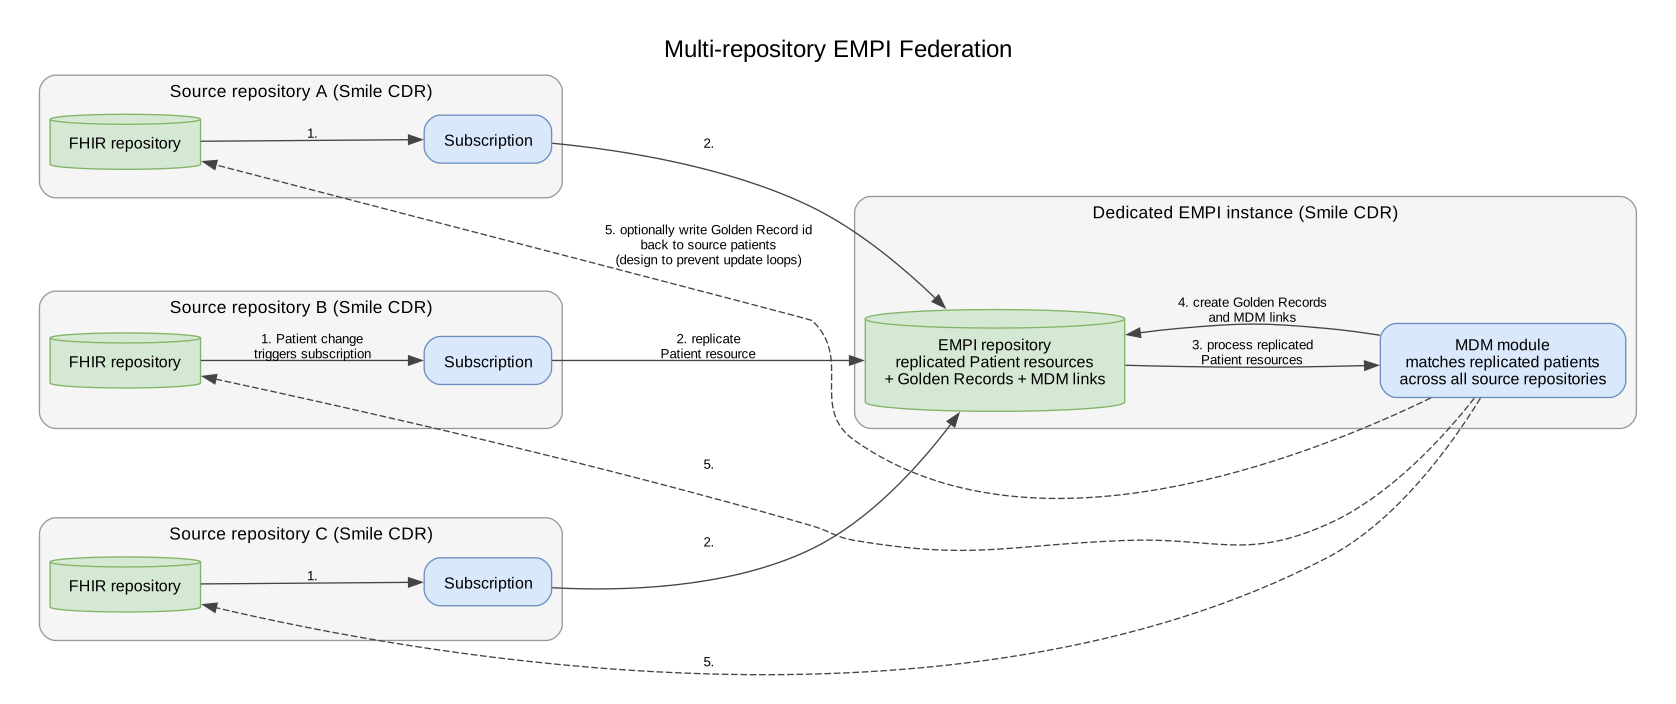
Multi-repository EMPI federation
In larger deployments, the same real-world patients may be represented in several independent FHIR repositories. One architecture pattern for managing identity in this situation is to replicate Patient resources from each repository to a dedicated EMPI instance of Smile CDR using Subscriptions. The EMPI instance runs MDM and maintains the links between matched patients across all of the source repositories, and can optionally write the id of its Golden Record back to the patient records in the originating systems. This is an architecture pattern assembled from existing capabilities rather than a packaged product feature, so it requires careful design — for example, preventing update loops between the source repositories and the EMPI instance.